Test your AI the way your customers use it

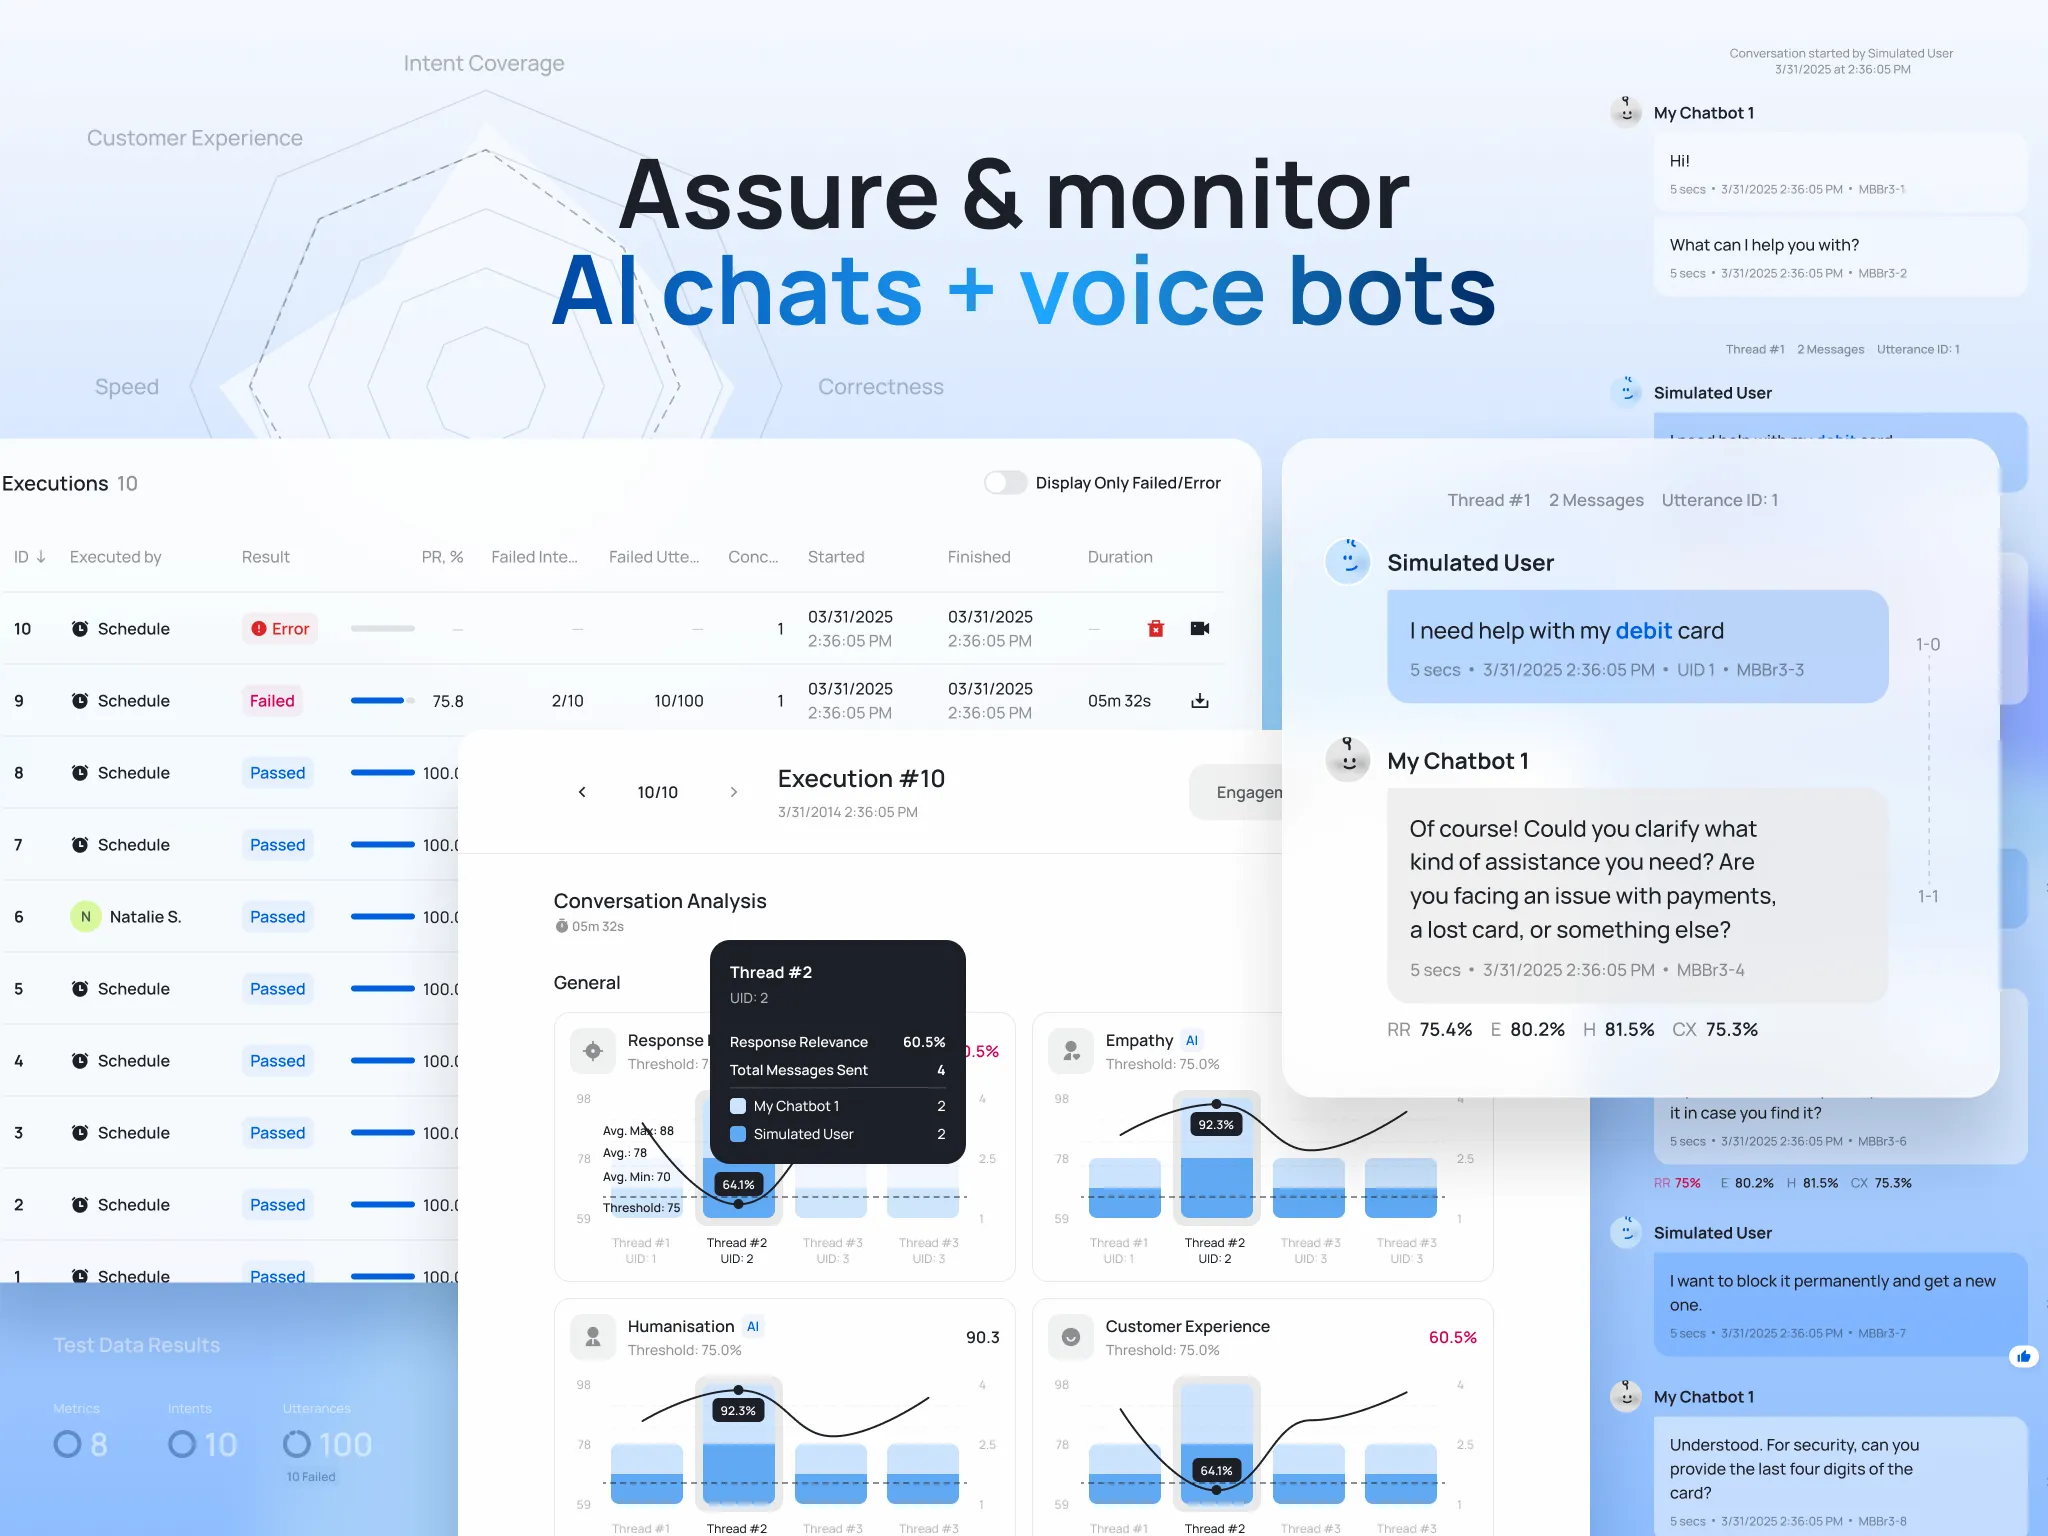
If an AI system talks to your customers, it needs testing every time it changes. We build evaluation suites and simulated customers that check each release across chat and voice, and dashboards that show quality in production.

Hero Figure

What is LLM evaluation?

Manual QA cannot keep up with AI releases

LLM evals Simulated customers Voice and chat Quality monitoring

LLM evaluation measures an AI system’s answers against agreed criteria on a fixed set of real cases, so you can tell whether a change made it better or worse. Without it, every prompt or model update is a guess.

On one conversational AI platform, our continuous testing layer found defects 88% faster, cut mean time to resolution by 60% and lowered QA spend by 48%.

01

Evaluation suite

Test cases from real conversations and tasks, scored for correctness, faithfulness to the retrieved sources, tone and escalation.
Decor Icon
02

Simulated customers

AI-driven users that rephrase, interrupt and change intent the way real callers and chat users do.

Decor Icon
03

Regression testing in CI

Every prompt, model, knowledge or flow change runs against the suite before it ships.

Decor Icon
04

Production quality dashboard

Resolution rate, failure clusters and hand-offs to people, tracked across channels.
Decor Icon

Start with the AI Quality Baseline:

Decor Icon

Week 1: Collect and define

We gather real interactions and agree on what a good answer looks like.

Week 1: Build the suite

We turn them into test cases and simulated customers for your channels.

Week 2: Run and score

We test your live system and score every case.

Week 2: Report

You get where it fails, how often, and what to fix first.

Chat assistants

Support, sales and internal assistants on web, app and messaging.

Decor Icon

Voice agents and IVR

Speech flows, interruptions, accents and hand-offs to people.

Decor Icon

RAG and knowledge answers

Retrieval recall, faithfulness to sources, citations and answers that go stale.

Decor Icon

Agent actions

Whether agents took the right steps with the right tools.

Decor Icon

Safety and policy

Prompt injection, data leakage and off-policy replies.
Decor Icon
Decor Icon

Cost and latency

Price per conversation and response time under load.
Decor Icon

Want a scored report on your live assistant in two weeks?

Decor Icon

Read how continuous AI testing found defects 88% faster and cut QA spend by 48%.

Decor Icon
How we engage

Start small, with a fixed scope

2 weeks · fixed fee

AI Production Readiness Review

Know what to build before you fund it. An evaluation baseline on your data, a target architecture, a run-cost model and a go/no-go plan.

6–9 weeks · team of 4

Pilot-to-Production Sprint

One workflow, live in production. Built or rebuilt, connected to your tools, with human approvals where the stakes are high and monitoring against the baseline.

Monthly · from 3 months

Forward-deployed AI engineers

Senior AI and data engineers who join your team, work in your tools and ship on your roadmap.

Part-time · monthly

Fractional AI CTO

Senior leadership for your AI roadmap: model and vendor choices, team design, architecture reviews and board reporting.

What clients say

Decor Icon

Top Ruby On Rails Developer

Certificate Pic
Decor Icon

Global

Certificate Pic
Decor Icon

Champion

Certificate Pic
Decor Icon

Top user experience company

Certificate Pic
Decor Icon

Top BI & Big Data company

Certificate Pic
Decor Icon

Top Software developers

Certificate Pic
Decor Icon

Teams that kept working with us

From my experience, it is hard to find a team who have both excellent technical and commercial skills. Busy Rebel has never let us down, so we continue to work with them. The most important criteria we have as a team is creating & maintaining high standards; Busy Rebel has this in spades.

Cormac Horan
Product & Strategy Director, Co-Founder at BillWinner

I've had the pleasure of working with a few software houses in the past, but none of them compares to the team at Busy Rebel. Their sense of mission and purpose is unparalleled, and their in-house skills are excellent. I always know that I can rely on them to get the job done, and done well, even if we are working remotely.

Fiachra Ó Comhraí
Former VP at Salesforce Inc., CEO at RenewalDiary

Busy Rebel provides backend and data engineers to scale the world's #1 student engagement CRM's internal team. The team builds new features and modules, builds data integration pipelines, and maintains the existing product. Extremely happy with the outcome.

Petar Djordjevic
CTO, at Element451

We've been partnering with Busy Rebel for almost 5 years now, and it is an exceptional software development partner. The responsiveness, solid experience, and good communication are impressive. Brilliant!

Torben Berner
Board Member at Destination Sjælland

Thanks to the contributions of Busy Rebel, our organization as a massive worldwide distributor has passed all phases of digital transformation, gained a competitive advantage, and somewhere has revolutionized our industry. Busy Rebel is extremely productive digital partner, and internal stakeholders are particularly impressed with the vendor's dedication to success and attention to detail.
Sascha Rosinger
CEO at Machinex Inc.

Tell us what you’re trying to ship

An engineer replies within one business day. We never share your details.

AI testing and evaluation: FAQ

Answers before you book

What is LLM evaluation?

Measuring an AI system’s outputs against agreed criteria on a fixed set of real cases, so each change can be compared with the last. For RAG that means scoring retrieval and generation separately: did the system find the right context, and is the answer faithful to it (Es et al., 2023). It combines automated checks, model-graded scoring and human review. Model graders are calibrated against human labels, because LLM judges show documented position and verbosity biases (Zheng et al., 2023).

What is the AI Quality Baseline?

A two-week, fixed-scope engagement: we test your live chat or voice assistant with simulated customers and give you a scored report of where it fails, how often and what to fix first.

Do you need access to our production system?

We need a test environment or a safe way to call the live assistant, plus a sample of real interactions. We sign an NDA and can work with anonymised data.

Can you test an assistant another vendor built?

Yes. The suite tests behaviour from the outside, so it works whoever built the assistant and whichever model it uses.